NVIDIA H200 NVL 141GB HBM3e — Enterprise AI GPU in Pakistan | AIOMATIC.PK
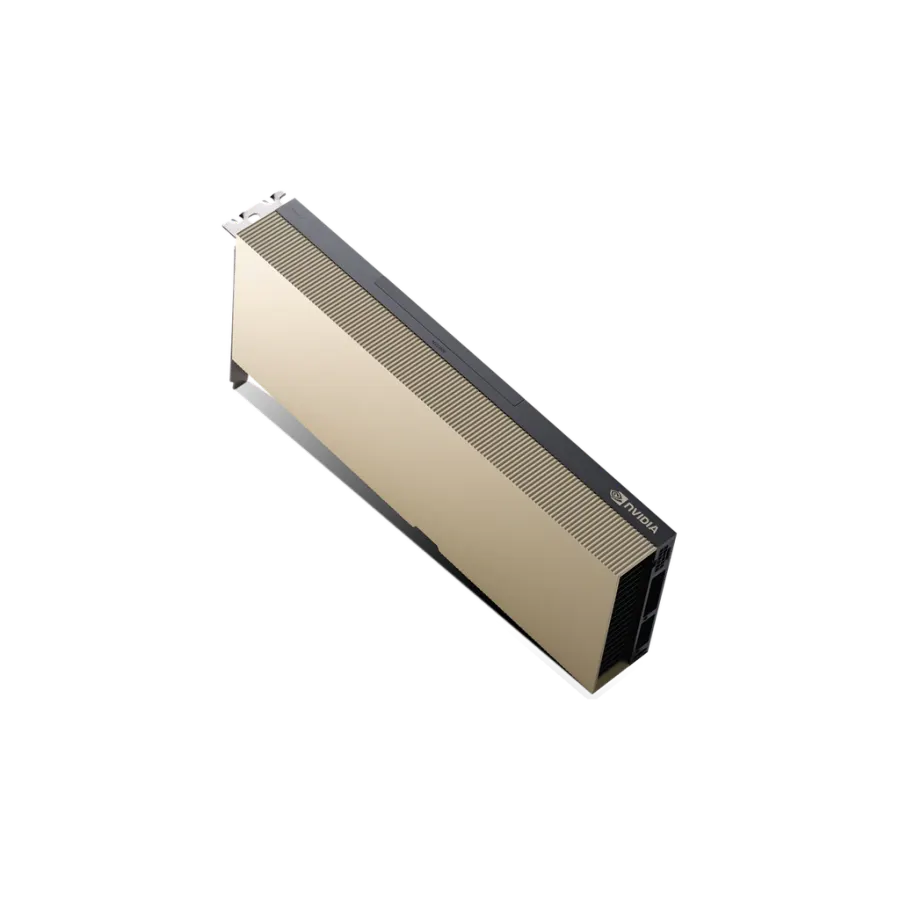
The NVIDIA H200 NVL is the premier dual-slot PCIe accelerator for massive language model inference and training, delivering an extraordinary 141GB of HBM3e memory and 4.8 TB/s of bandwidth. Available for procurement in Pakistan exclusively through AIOMATIC.PK.
1. NVIDIA H200 NVL: The Ultimate High-Bandwidth Accelerator
Modern reasoning models, multimodal vision-language architectures, and high-parameter foundational models face a defining physical constraint: memory bandwidth. During autoregressive token generation, neural network weights must be pulled from memory into compute cores for every single token generated. Standard GDDR memory architectures simply cannot saturate modern tensor cores.
The NVIDIA H200 NVL (141GB HBM3e) shatters this memory wall. By integrating six stacks of ultra-fast HBM3e silicon, the H200 NVL pushes throughput to an astonishing 4.8 Terabytes per second, delivering up to a 2x inference speedup over the H100 at equivalent power consumption.
For research labs, sovereign compute clusters, and Tier-1 corporations in Pakistan, AIOMATIC.PK delivers direct enterprise procurement, duty-paid importation, and cluster-level configuration for the H200 NVL. Explore our catalog at AIOMATIC Compute Catalog.
2. Technical Architectural Breakdown
| Metric | NVIDIA H200 NVL | NVIDIA H100 PCIe | NVIDIA B200 PCIe |
|---|---|---|---|
| VRAM Capacity | 141 GB HBM3e | 80 GB HBM2e | 192 GB HBM3e |
| Memory Bandwidth | 4.8 TB/s | 2.0 TB/s | 8.0 TB/s |
| FP8 Tensor Throughput | 1,671 TFLOPS | 1,513 TFLOPS | 4,500 TFLOPS |
| NVLink Bandwidth | 900 GB/s Bidirectional | 600 GB/s | 1,800 GB/s |
| TDP (Cooling) | 350W - 400W (Air-cooled) | 350W (Air-cooled) | 1000W (Liquid/Air) |
3. 2-GPU, 4-GPU, and 8-GPU Cluster Configurations
AIOMATIC.PK architects turn-key H200 NVL clusters tailored for high-density inference and fine-tuning:
- Dual H200 NVL Inference Node: 282GB pooled HBM3e memory across 900 GB/s NVLink. Runs DeepSeek-R1 (671B MoE with active 37B routing) or LLaMA 3.1 405B at INT4 quantization with exceptional tokens-per-second velocity.
- Quad H200 NVL 4U Server: 564GB pooled HBM3e. The premier workstation supercomputer for local university AI labs and enterprise banking risk engines in Pakistan.
- Octo H200 NVL High-Density Rack: Over 1.1 Terabytes of aggregate high-speed VRAM, providing cloud-tier foundational training capabilities directly inside Pakistani data centers.
View hardware specifications and chassis options in our Hardware Index.
4. Procuring the H200 NVL in Pakistan with AIOMATIC.PK
Procuring bleeding-edge accelerators requires vetted supply chains to safeguard against grey-market cards, revoked warranties, and customs confiscation. AIOMATIC.PK guarantees:
- 100% OEM brand-new factory-sealed hardware with verified serial numbers registered on NVIDIA partner portals.
- Clear customs transit via Karachi Air Freight with full commercial invoice declarations, Federal Board of Revenue (FBR) GST compliance, and formal tax deduction documentation.
- On-site hardware deployment, IPMI baseline configuration, and stress testing with vLLM, TensorRT-LLM, and PyTorch CUDA benchmarks.
Frequently Asked Questions
What is the price of the NVIDIA H200 NVL 141GB in Pakistan?
The NVIDIA H200 NVL 141GB is quoted on request through AIOMATIC.PK. As an ultra-tier enterprise accelerator, pricing depends on order volume, server integration specifications, and prevailing foreign exchange rates. AIOMATIC.PK offers formal proforma quotations with full FBR customs clearance and commercial tax invoicing. Contact +923322227426 on WhatsApp for current availability.
How does the H200 NVL compare to the standard H100?
The H200 NVL upgrades the memory capacity from 80GB HBM2e to 141GB HBM3e (a 76% increase) and expands memory bandwidth from 2.0 TB/s to 4.8 TB/s (a 140% increase). This eliminates memory-bound latency in 70B+ model inference, doubling generative output tokens per second compared to the H100.
Can a single NVIDIA H200 NVL run LLaMA 3 70B in FP16?
Yes. LLaMA 3 70B requires approximately 140GB in uncompressed 16-bit floating point precision. With 141GB of HBM3e memory, a single H200 NVL card can load and serve the entire unquantized model without weight sharding across multiple GPUs.
Does the H200 NVL support multi-GPU NVLink clustering?
Yes. The H200 NVL features dual NVLink bridges providing up to 900 GB/s bidirectional inter-GPU bandwidth. Up to four dual-slot H200 NVL cards can be paired inside a single standard enterprise 4U server chassis for a combined 564GB of ultra-fast HBM3e memory.
What server chassis and power supply are required for H200 NVL?
The H200 NVL requires server chassis with high-static-pressure front-to-back fans for passive cooling, PCIe Gen5 x16 electrical slots, and dual/quad 2000W+ redundant power supplies (such as Supermicro 2U or 4U rackmount servers). AIOMATIC.PK provides pre-validated, turnkey H200 NVL server systems.
Procure Enterprise AI Compute in Pakistan
Need custom GPU accelerators, turnkey rack clusters, 64-core bare-metal cloud servers, or autonomous AI agent swarms? Speak directly with AIOMATIC.PK enterprise infrastructure engineers.